
Introduction
In the domain of generative artificial intelligence, specifically Large Language Models (LLMs), a prompt is often colloquially defined as the text input provided by a user. However, from a computer science perspective, a prompt is more accurately described as an input sequence of tokens that steers the probability distribution of the model's autoregressive token generation. Understanding what makes a prompt "good" requires moving beyond creative writing and looking into the underlying mechanics of Transformer architectures, attention mechanisms, and latent space navigation.
How LLMs Process Your Input
To write optimal prompts, you must understand how an LLM processes information. When you submit a prompt, the model does not read it as a human does. Instead, the input undergoes several distinct phases:
- Tokenization: The raw text is parsed into smaller units called tokens, which are mapped to numerical IDs based on a pre-defined vocabulary.
- Embedding: These token IDs are converted into high-dimensional vectors, placing them within a continuous vector space (latent space).
- Attention Mechanism: The Transformer model applies self-attention, calculating mathematical relationships between every token in the sequence. This determines the context and weight of each word relative to others.
- Probability Distribution: Based on the attention weights, the model calculates the probability distribution for the next most likely token in the sequence, continuing this loop until a stop token is reached.
A good prompt is one that minimizes ambiguity within this mathematical space, effectively constraining the model's attention to the exact domain of knowledge and style required for the task.
The Structural Components of a Production-Grade Prompt
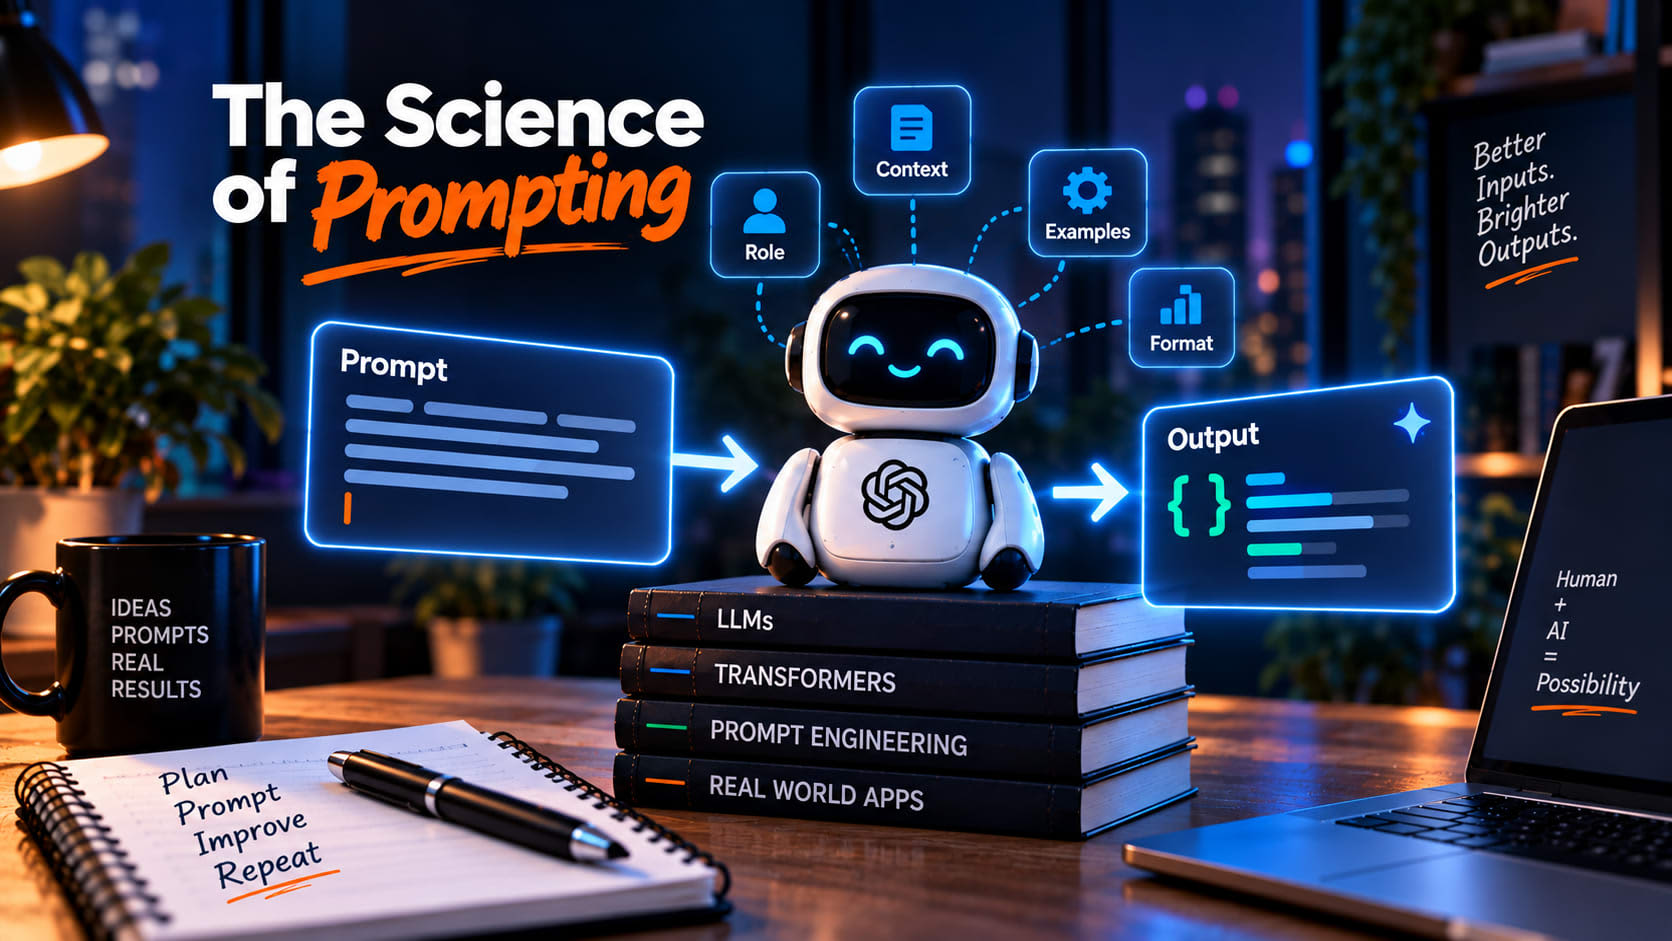
An ad-hoc prompt might contain a simple question, but a production-grade prompt designed for deterministic, high-quality outputs consists of four core structural pillars:
1. System Instructions (Persona and Role)
This establishes the boundaries of the latent space the model should operate within. By defining a specific persona, you instruct the model to prioritize certain subsets of its training data.
# Good System Instruction
You are a senior systems engineer specializing in Linux kernel optimization. Respond only with technically precise, low-level explanations.
2. Context and Grounding Data
LLMs are prone to hallucination when relying solely on parametric memory (the knowledge stored in their weights). Providing explicit context or grounding data ensures the model operates on verified information. This is the foundation of Retrieval-Augmented Generation (RAG).
# Grounding Context
Using only the provided system metrics below, diagnose the performance bottleneck:
[Metrics: CPU utilization 98%, I/O wait 45%, Memory usage 40%]
3. Input Data (The Payload)
This is the actual variable data that needs processing. Keeping the input payload clearly separated from instructions prevents prompt injection and parsing errors.
4. Output Formatting and Constraints
To use LLM outputs in software pipelines, the response must be structured. Specifying constraints (such as JSON schemas or length limits) is critical.
# Output Constraints
Return the output strictly as a valid JSON object matching this schema:
{
  "status": "string",
  "error_code": "integer"
}
Do not include any markdown formatting, preambles, or postscripts.
Advanced Prompting Methodologies
When simple zero-shot prompting (asking a question directly) fails, advanced techniques can significantly improve reasoning capabilities.
Few-Shot Prompting
Few-shot prompting leverages the in-context learning capabilities of LLMs. By providing a few input-output exemplars within the prompt, you demonstrate the desired logic and formatting without fine-tuning the model.
Input: User cannot log in. Error code 403.
Output: Category: Authentication | Severity: High | Action: Verify OAuth token.

Input: Page loads slowly. Response time 5000ms.
Output: Category: Performance | Severity: Medium | Action: Check database query latency.

Input: API returns 502 Bad Gateway.
Output:
Chain-of-Thought (CoT) Prompting
For complex logical, mathematical, or reasoning tasks, forcing the model to generate intermediate reasoning steps before outputting the final answer dramatically improves accuracy. This is known as Chain-of-Thought prompting.
Problem: A server rack has 4 nodes. Each node has 2 CPUs. Each CPU has 16 cores. We need to allocate 8 cores per virtual machine. How many virtual machines can we host on the rack?
Reasoning: Let's calculate step-by-step.
1. Total CPUs in the rack = 4 nodes * 2 CPUs/node = 8 CPUs.
2. Total cores in the rack = 8 CPUs * 16 cores/CPU = 128 cores.
3. Total virtual machines = 128 cores / 8 cores/VM = 16 VMs.
Answer: 16
Production Concerns and Trade-offs
While highly detailed prompts yield better results, engineering teams must balance quality against operational constraints:
- Token Latency: Larger prompts increase Time-to-First-Token (TTFT) and overall inference time, as the self-attention mechanism scales quadratically with sequence length.
- Financial Cost: Commercial LLM APIs charge per input and output token. Overly verbose prompts can exponentially increase operational costs.
- Context Window Degradation: Although modern models support massive context windows, attention degradation can occur, causing the model to miss information placed in the middle of long prompts (the "lost in the middle" phenomenon).
Conclusion
A good prompt is not a creative writing exercise; it is an exercise in constraint satisfaction and probability steering. By structuring prompts with clear system roles, explicit grounding data, distinct payloads, and strict output constraints, developers can build reliable, deterministic, and highly efficient AI-powered systems.