
PDFella
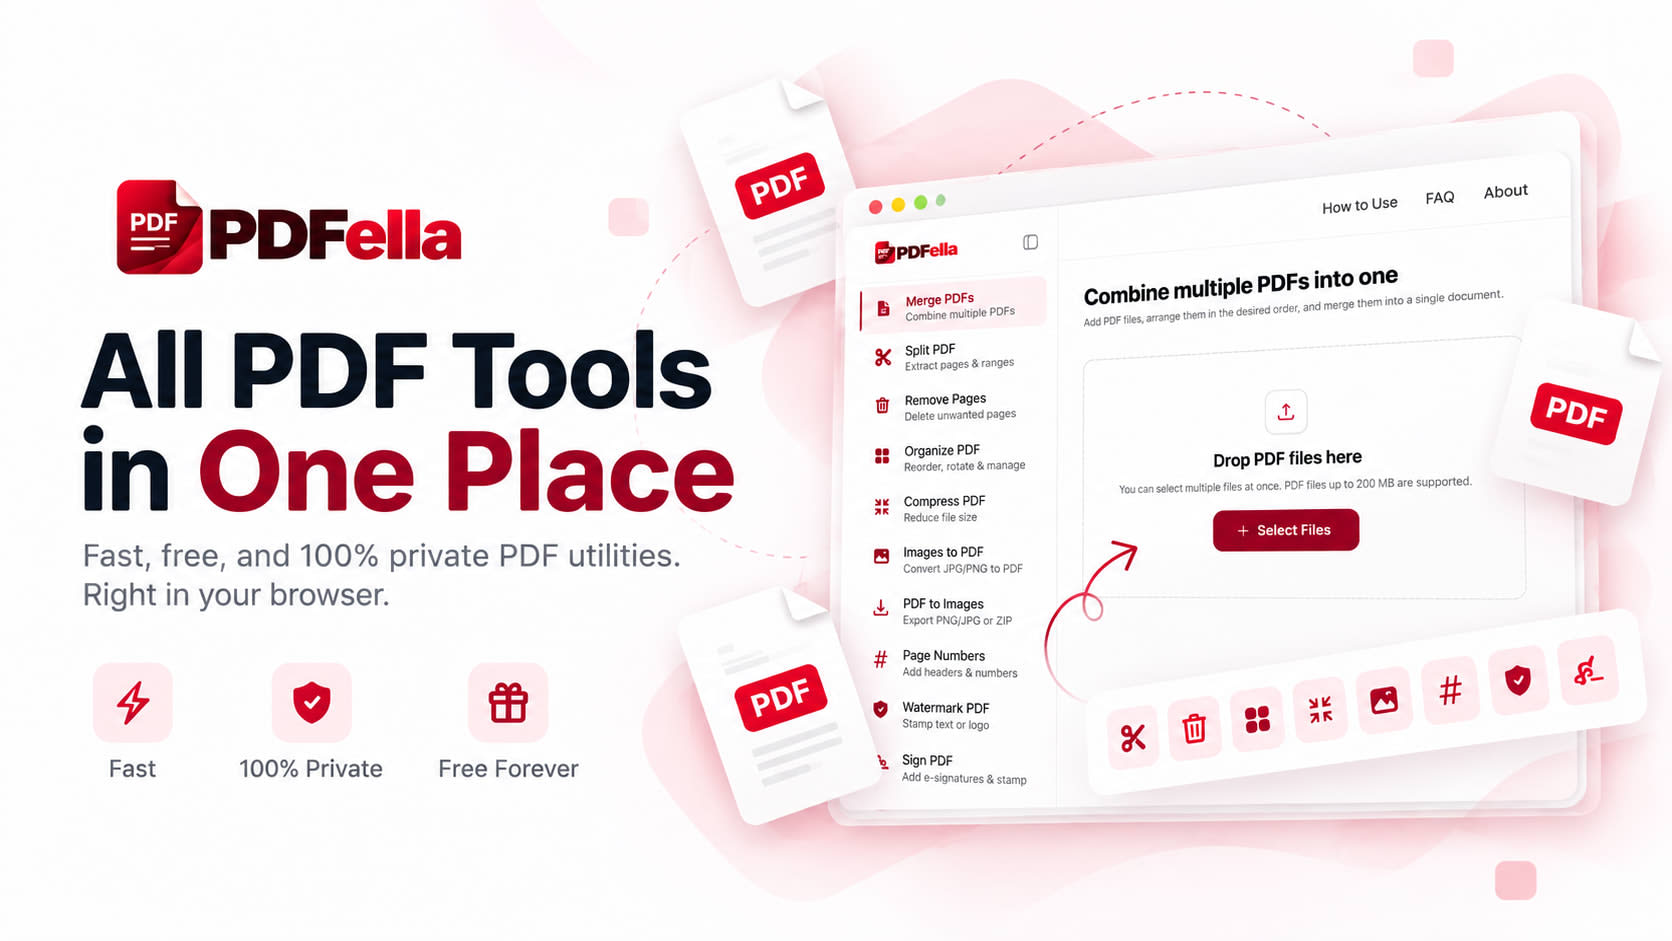
A fast, client-side PDF utility suite that runs entirely in the browser. Documents are processed locally on the user's device using WebAssembly and HTML5 APIs—no files are uploaded to any server.
Live application: pdfella.tharidulakmal.com
Author: Tharidu Lakmal
Overview
Most online PDF tools require uploading documents to remote servers for processing, creating privacy risks for legal, financial, and personal files. PDFella executes all document parsing, rendering, modification, and generation directly inside the client's browser environment using pdf-lib and pdfjs-dist.
Core Highlights
Zero Server Uploads: File buffers stay inside the browser's JavaScript memory and garbage-collect on completion.
No Account Required: Immediate access to all features without sign-up, subscriptions, or document quotas.
No Watermarks: Exported documents retain original quality without forced branding.
Offline Capable: Works without an internet connection once the static application assets and Web Worker are cached.
Memory & Security Safeguards: File header verification (magic bytes), 100MB per-file safety guardrails, and client heap monitoring.
Available Tools
ToolRouteDescriptionEngineMerge PDF/mergeCombine multiple PDF files into a single document with drag-and-drop sequencing and page-1 thumbnail previews.pdf-libSplit PDF/splitExtract specific pages or custom ranges (1-3, 5, 8-12) with two-way synchronized visual card selection.pdf-lib + pdfjs-distRemove Pages/removeDelete unwanted or sensitive pages from a document with safety checks preventing complete page deletion.pdf-lib + pdfjs-distOrganize PDF/organizeVisual grid to reorder pages via drag-and-drop, rotate pages by 90° increments, duplicate, or delete.pdf-lib + @dnd-kitCompress PDF/compressReduce document file sizes via client-side canvas rasterization across three compression tiers (Extreme, Recommended, Less).pdfjs-dist + pdf-libPDF to Images/pdf-to-imageExport document pages as high-resolution PNG or JPG images, with single-page downloads or batch ZIP export.pdfjs-dist + Canvas APIImage to PDF/image-to-pdfConvert JPG, PNG, WebP, and BMP files into a unified PDF with custom margins, orientations, and page sizes (A4, Letter, Fit).pdf-libAdd Page Numbers/page-numbersStamp Bates or header/footer numbering across 6 quadrant positions with customizable numbering schemes and cover page exclusion.pdf-libWatermark PDF/watermarkApply custom text watermarks or image stamps with configurable opacity, rotation angles, font sizes, and cover page skips.pdf-libSign PDF/signSign documents by drawing smooth vector strokes (perfect-freehand), typing styled script signatures, or uploading image signatures.pdf-lib + perfect-freehand
Technical Architecture
                          ┌────────────────────────┐
                          │     User's Browser     │
                          └───────────┬────────────┘
                                      │
              ┌───────────────────────┴───────────────────────┐
              │                                               │
              ▼                                               ▼
   ┌──────────────────────┐                       ┌──────────────────────┐
   │    Document Parse    │                       │   Worker Rendering   │
   │      (pdf-lib)       │                       │     (pdfjs-dist)     │
   ├──────────────────────┤                       ├──────────────────────┤
   │ • Binary manipulation│                       │ • Canvas raster      │
   │ • Page extraction    │                       │ • Page thumbnails    │
   │ • Watermarking/Sign  │                       │ • Off-thread worker  │
   └──────────┬───────────┘                       └──────────┬───────────┘
              │                                               │
              └───────────────────────┬───────────────────────┘
                                      │
                                      ▼
                          ┌────────────────────────┐
                          │   Local File Export    │
                          │   (Blob / Object URL)  │
                          └────────────────────────┘
1. In-Memory Document Manipulation
Document manipulation (merging, slicing, page removal, Bates numbering, watermarks) runs in WebAssembly / JavaScript via pdf-lib. Uploaded files are converted into ArrayBuffer instances and modified directly in client RAM.
2. Off-Thread Canvas Rendering
PDF page thumbnails and visual previews are generated using Mozilla's pdfjs-dist. Rendering runs with a dedicated Web Worker (public/pdf.worker.min.mjs) to keep the UI thread responsive during multi-page rendering.
3. Smooth Signature Capture
The signing canvas uses perfect-freehand to calculate pressure-sensitive polygonal paths from raw mouse and touch inputs, converting strokes into high-resolution SVG/PNG data URLs for embedding into PDF coordinate spaces.
4. Zero Network Transmission
All download actions generate local blob: URLs via URL.createObjectURL() and trigger direct downloads through programmatic anchor elements. No payload ever leaves the client device.
Security & Reliability Guardrails
Magic Byte Verification: Verifies the binary file header starts with
%PDF-(or valid image headers) to prevent file extension spoofing.Size Bounds: Implements a client-side 100MB threshold per document to prevent browser tab crashes from unconstrained memory allocation.
Filename Sanitization: Cleans output file names by stripping control characters and path traversal patterns (
../).Memory Pressure Monitoring: Tracks
performance.memory(where supported) to warn users when JavaScript heap consumption nears 80%, falling back to lightweight placeholder cards when resources are constrained.Off-Thread Cancellation: Cancels running PDF.js rendering tasks when switching tabs or dropping a new file, preventing resource leaks.
Tech Stack
Framework: Next.js 16 (App Router, React 19)
Language: TypeScript (Strict mode)
Styling: Tailwind CSS v4
PDF Core:
pdf-lib&pdfjs-distDrag & Drop:
@dnd-kitVector Strokes:
perfect-freehandAnimation:
framer-motionNotifications:
sonnerPackage Manager:
pnpm
Project Structure
├── app/                        # Next.js App Router pages and metadata
│   ├── layout.tsx              # Root layout, fonts, and global metadata
│   ├── page.tsx                # Homepage view (PDF Merger default)
│   ├── merge/                  # /merge route
│   ├── split/                  # /split route
│   ├── remove/                 # /remove route
│   ├── organize/               # /organize route
│   ├── compress/               # /compress route
│   ├── pdf-to-image/           # /pdf-to-image route
│   ├── image-to-pdf/           # /image-to-pdf route
│   ├── page-numbers/           # /page-numbers route
│   ├── watermark/              # /watermark route
│   ├── sign/                   # /sign route
│   ├── about/                  # About page
│   ├── faq/                    # Frequently asked questions
│   └── privacy/                # Privacy policy documentation
├── components/
│   ├── features/pdf/           # PDF tool view components and modals
│   │   ├── MergePdfView.tsx
│   │   ├── SplitPdfView.tsx
│   │   ├── RemovePagesView.tsx
│   │   ├── OrganizePdfView.tsx
│   │   ├── CompressPdfView.tsx
│   │   ├── PdfToImageView.tsx
│   │   ├── ImageToPdfView.tsx
│   │   ├── PageNumbersView.tsx
│   │   ├── WatermarkPdfView.tsx
│   │   ├── SignPdfView.tsx
│   │   └── signature/          # Signature canvas & placement controls
│   ├── layout/                 # Shell components (Header, Footer, Sidebar)
│   ├── ui/                     # Design system primitives (Buttons, Cards, Modals)
│   └── seo/                    # Structured data (JsonLd) and SEO components
├── lib/
│   ├── pdf/                    # Core PDF processing and validation modules
│   │   ├── merge.ts            # PDF combination logic
│   │   ├── split.ts            # Page range extraction
│   │   ├── remove.ts           # Page deletion
│   │   ├── organize.ts         # Page reordering & rotation
│   │   ├── compress.ts         # Raster recompression
│   │   ├── pdfToImage.ts       # Canvas raster to PNG/JPG
│   │   ├── imageToPdf.ts       # Image embedding to PDF
│   │   ├── pageNumbers.ts      # Bates / page stamping
│   │   ├── watermark.ts        # Text and logo overlays
│   │   ├── sign.ts             # Electronic signature injection
│   │   ├── render.ts           # PDF.js thumbnail generation
│   │   ├── validation.ts       # Magic byte and buffer validators
│   │   └── zip.ts              # In-browser ZIP bundling
│   └── utils.ts                # General helper utilities
├── public/                     # Static assets, icons, and pdf.worker.min.mjs
└── types/                      # Shared TypeScript definitions
Getting Started
Prerequisites
Installation
Clone the repository and install dependencies:
git clone git@github.com:tharidulakmal/pdfella.tharidulakmal.com.git
cd pdfella.tharidulakmal.com
pnpm install
Development Server
Start the local Next.js development server:
pnpm devOpen http://localhost:3000 in your browser.
Production Build
Create an optimized production build:
pnpm buildRun the built application locally:
pnpm startCode Quality & Linting
Run ESLint to check for code standards:
pnpm lintBrowser Compatibility
PDFella requires modern browsers supporting ECMAScript 2022+, HTML5 Canvas, and Web Workers:
Google Chrome / Chromium-based browsers (Edge, Brave, Opera)
Mozilla Firefox
Apple Safari (macOS & iOS)
License & Attribution
Designed and built by Tharidu Lakmal. All rights reserved.